
Platform
ADE Collect: offline mobile data collection
Our field-collection app, built to work offline and check quality at the point of entry.

Much of the population communicates orally first, in national languages. Digital services must be able to understand them.
Platform
Our field-collection app, built to work offline and check quality at the point of entry.

Internal tool
A rules engine that measures the completeness, uniqueness and consistency of our clients' datasets.

Open data
A weekly survey of market prices, published as open data and available by SMS.

Platform
The learning space for Academy and Data Talent Pipeline learners: courses, exercises on real data and progress tracking.

Internal tool
An online assessment that places an organisation on five dimensions and feeds our annual barometer.

AI
An agent that tracks data-protection texts in West Africa and answers compliance questions.
Platform
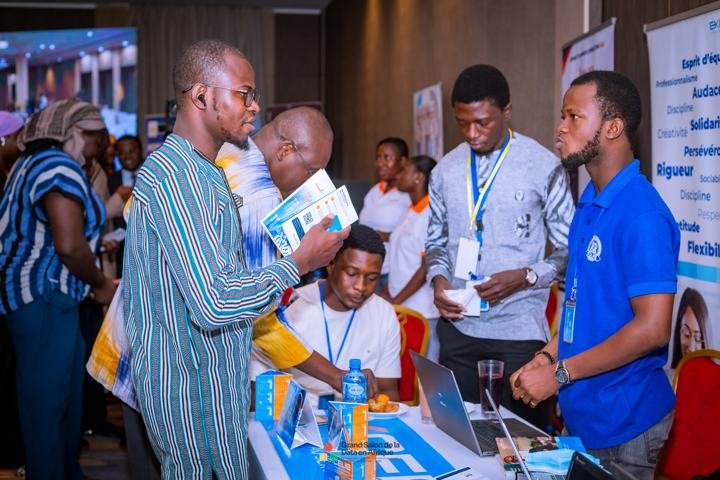
Registration, QR badges, programme and satisfaction measurement for the Africa Data Fair.
Free first conversation, reply within one business day.
ADE assistant
Instant replies · team available 8am–5:30pm